
Performance#
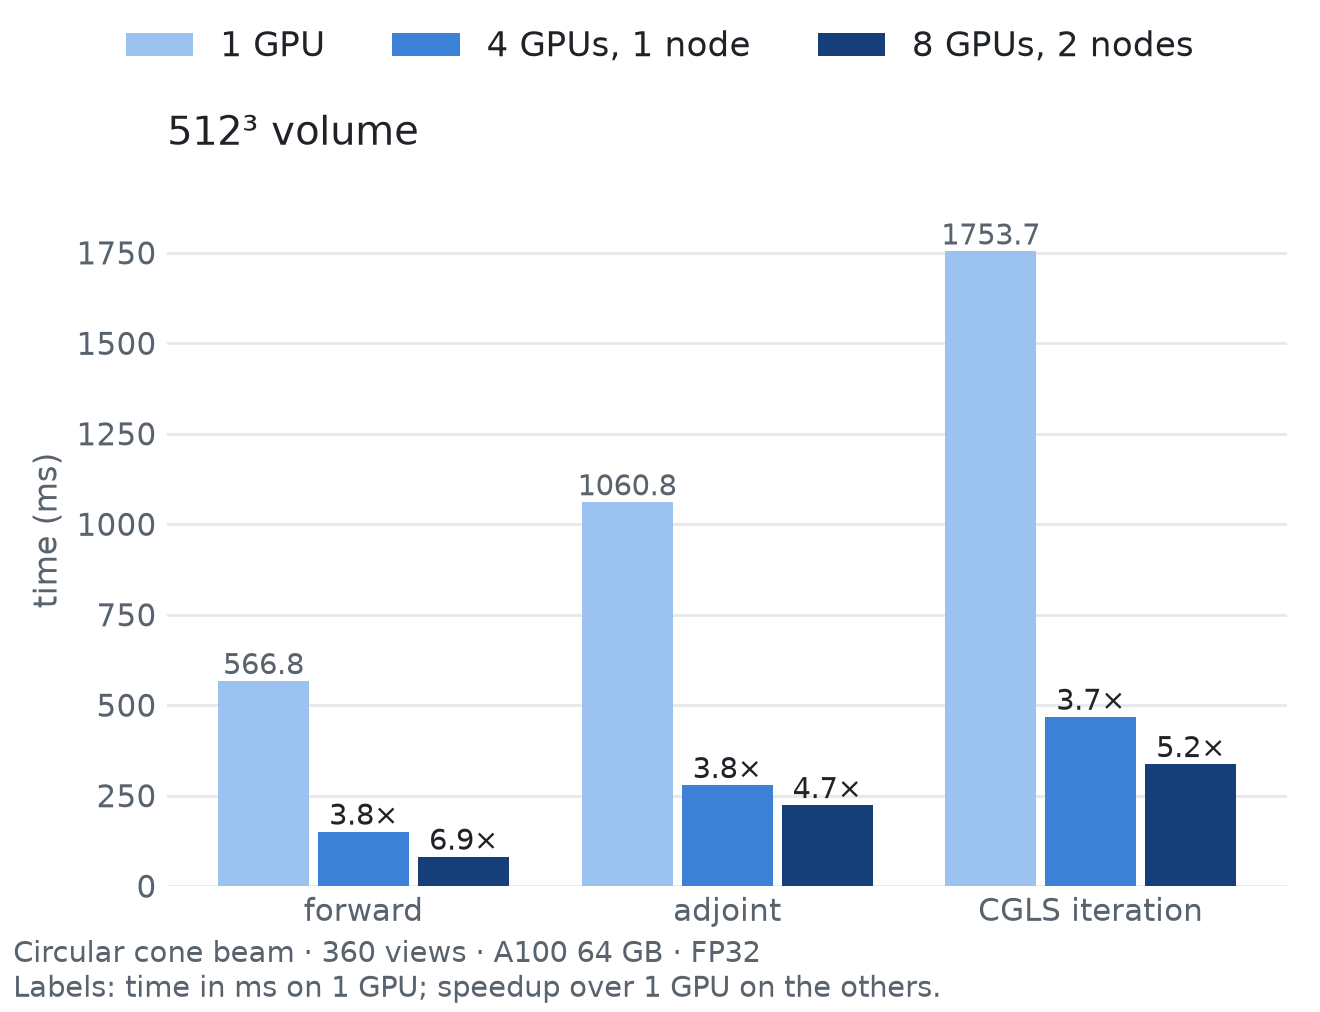
Time per forward projection, adjoint and CGLS iteration for a 512³ volume on 1, 4 and 8 GPUs. Run the same workload with examples/benchmark_scaling.py.
512³ volume |
1 GPU |
4 GPUs, 1 node |
8 GPUs, 2 nodes |
|---|---|---|---|
Forward projection |
566.79 ms |
150.76 ms (3.8×) |
81.58 ms (6.9×) |
Adjoint (backprojection) |
1060.77 ms |
279.37 ms (3.8×) |
224.04 ms (4.7×) |
CGLS iteration |
1753.73 ms |
468.09 ms (3.7×) |
337.39 ms (5.2×) |
diffct 2.4.3, FP32, A100 64 GB GPUs; circular cone beam, 360 views, 1024×768 detector, pitch 1.25. Default memory settings, without an imposed allocator cap. Projection times are medians of seven samples after three warmups. CGLS uses three ten-iteration solves after a two-iteration warmup; the median includes initialization and is divided by ten. Raw samples and configuration: scaling.json.